How Causal Machine Learning Simulations Guide Method Selection
What the simulations say about choosing a causal method
The main lesson is less about finding a clever algorithm than about asking the right causal question. Across nine simulations, each repeated 40 times with a known true effect, methods failed together when the causal story was wrong. Flexible models can handle complicated relationships; they can’t recover an important factor that was never measured or correct for a variable that shouldn’t have been included.
The results are aimed at data scientists and analysts estimating the effect of an intervention such as a call, discount, or campaign. They compare causal machine learning with linear models (LM), generalized linear models (GLM), and gradient-boosted machines (GBM). The findings are pointed:
- Get the data and causal structure right first. When a model includes the wrong variable or leaves out an important influence, every method is wrong. Domain knowledge or a valid instrument can help; a more flexible algorithm cannot. (Cases 4 and 5.)
- For an average effect, causal ML earns its keep when confounders act nonlinearly. In that setting, LM is biased and Double ML comes close to the truth. The gain comes from its “adjust first, estimate second” construction, not from any one machine learning algorithm. (Case 3.)
- Predicting risk doesn’t tell you whom an intervention will help. In the cancellation example, targeting the customers most likely to leave performs worse than random selection: these customers are especially hard to retain. (Case 7.)
- Choosing the right people can be easier than estimating the effect’s size. A GLM can rank units correctly while still getting the effect magnitude wrong. (Case 9.)
- Causal forests are useful when effects vary and their pattern is unknown. They help estimate the effect for each unit, but a well-specified GLM does better in a simple setting. (Cases 6, 8, and 9.)
If you’re deciding what to use, start with the guide below. The methodology section explains the terms, formulas, strengths, weaknesses, and ways to check a result when the true effect is unknown. The simulation section lays out the nine cases, their data and results, and the lesson from each. Numbered citations such as [5] refer to the article’s reference list.
Choose the question before the method
The guide’s sequence matters. First establish what decision you’re making, then how treatment was assigned, then whether the effect can be identified from the available data. Only after those checks does the choice of algorithm make sense. No algorithm can settle the first three steps.
The examples use a fictional online fitness subscription app with training plans and classes. “Unit” means whatever receives treatment: a customer, person, contract, or branch.
Here are the terms the guide uses:
- A/B test: Treatment was assigned at random, so treated and untreated units are comparable.
- Non-random assignment: Rules or business judgment determined treatment. The resulting observational data contain groups that may already differ.
- Confounder: A measured or unmeasured variable that affects both treatment assignment and the outcome. If it’s missing from the data, no algorithm can substitute for it.
- Instrument: A random nudge, such as a randomly sent invitation, that changes the chance of treatment and affects the outcome only through that treatment. It can support an estimate when a confounder is missing.
- Average treatment effect (ATE): One effect for the population as a whole; it answers whether the intervention works on average.
- Ranking, or targeting: Ordering units by estimated effect to decide whom to treat—for example, the 30% expected to benefit most. A model can rank people correctly while overestimating or underestimating every effect by the same amount.
- Conditional average treatment effect (CATE): The estimated effect for an individual unit, useful when weighing costs and benefits person by person. Getting the size right is a stricter requirement than getting the ranking right; Case 9 demonstrates the difference.

In the guide’s diagrams, blue marks a question, green a recommendation, and red a stopping point.
Step 1: What decision are you making?
- To ask whether an intervention works on average, estimate the ATE and continue to Step 2.
- To decide whom to treat, rank units by their effects and continue to Step 2.
- To estimate the effect size for a particular unit—for example, for a unit-level cost-benefit decision—estimate the CATE and continue to Step 2.
- To predict who will cancel without an intervention, use a pure GBM for risk prediction. That answers a different question and is unsuitable for intervention decisions. In Case 7, targeting the top 30% by risk produced uplift of 0.037, worse than chance.
- To choose how strongly to treat someone, such as setting a discount level, you need a dose-response curve. That topic is discussed methodologically in the conclusion; it was not simulated.
Step 2: How was treatment assigned?
- If treatment was randomized, as in an A/B test or lottery, identification is secured; proceed to Step 4.
- If business rules or judgment determined treatment, proceed to Step 3.
- If treatment was randomly assigned but some assigned units never received it—for example, a customer was assigned a call but couldn’t be reached—the comparison by assignment estimates the effect of the assignment. To estimate the effect of treatment itself, use assignment as an instrument with 2SLS (Case 5 [5]). This situation wasn’t simulated.
Step 3: Can the effect be identified without random assignment?
This is where many projects break down. The key decisions concern which variables belong in the model, and they depend on how treatment and outcome came about—not on which algorithm you run.
In the diagrams,  marks treatment,
 marks the outcome, and
 marks the variable being considered.
- Confounder: \(T \leftarrow X \rightarrow Y\). The variable \(X\) is a common cause of treatment and outcome, so treated and untreated units differ before treatment. For example, older customers might be more likely to receive a call and might also cancel at a different rate. Include the confounder; otherwise its influence can be mistaken for a treatment effect. If its effect is nonlinear, model it in the right form too (Cases 2 and 3).
- Mediator: \(T \rightarrow X \rightarrow Y\). Treatment affects the outcome through \(X\), which arises after treatment. A call might prompt a customer to set up a training plan, which in turn helps them stay. Leave the mediator out when estimating the total effect; including it removes the part of the effect that passes through \(X\). In Case 4, including it biases all methods.
- Collider: \(T \rightarrow X \leftarrow Y\). Both treatment and outcome cause \(X\). For example, a call and a cancellation could each lead a customer to appear in a complaint log. Don’t control for the collider: doing so creates a spurious relationship between treatment and outcome. The article doesn’t simulate a separate collider case; the rule is the same as for mediators.
The practical rule is to include pre-treatment variables that help determine treatment, and exclude variables that arise after treatment. The data alone can’t tell you whether a variable is a confounder or a mediator; that requires knowledge of the process. For an overview of good and bad control variables, see [19]. DAGitty can help: draw the process as a directed acyclic graph and the program identifies the required variables [26].
- Check whether a confounder is missing. The data can’t prove that none is missing. A placebo test checks whether treatment appears to affect an outcome it cannot plausibly influence; the expected effect is zero (Case 5). An E-value describes how strong an unmeasured confounder would need to be to explain away the estimated effect [20]. DoWhy runs such checks automatically [27].
- If one is missing, look for an instrument. A valid instrument is a random nudge that affects the outcome only through treatment. Use 2SLS for a constant effect or an instrumental forest for effects that vary (Case 5). Instrument validity can’t be checked from the data. If there’s no instrument, don’t make a causal claim: report an association, not an effect. Before-and-after data or a threshold may allow difference-in-differences or regression discontinuity; those methods are covered later but weren’t simulated.
- Check overlap. Each relevant group needs both treated and untreated units. Inspect the propensity histogram; where propensities approach 0 or 1, restrict the analysis to the region with overlap. Otherwise AIPW and other weighting estimators can become unstable (Case 3, †). The effects of restricting the population weren’t simulated.
Step 4: Match the method to the question and data
Find the data situation and target question in the table. It assumes you passed the identification and overlap checks, and that you’re estimating an effect rather than predicting risk. For a few hundred units, use the small-data guidance in row 2. The decision tree marks questions in blue, recommendations in green, and stopping points in red; “Var.” means variables.

| # | Data situation | Question | Recommendation | Cross-check | Avoid | Evidence |
|---|---|---|---|---|---|---|
| 1 | A/B test | Average effect | Compare means. LM with T + X is useful at most for reducing variance. | — | — | Cases 1, 6–8 |
| 2 | A/B test, a few hundred observations | Ranking or effect per unit | First check whether effects vary. Without a strong prior hypothesis, assign the average effect to everyone; LM with T + X had CATE-RMSE 0.141 in Case 1. | Causal forest, 0.21; it estimated an almost constant effect when the true effect was constant. | T-learner and GBM S-learner, with CATE-RMSE 0.72 and 0.51; they created apparent differences from noise. | Case 1 |
| 3 | A/B test, few variables, simple form plausible | Ranking or effect per unit | GLM with T × X: CATE-RMSE 0.127, versus 0.24 for causal forest. | S-learner; causal forest | Pure risk model (Case 7) | Cases 6, 7 |
| 4 | A/B test, many variables, form unknown | Ranking | S-learner: top-30% uplift 1.64, close to the oracle’s 1.65. | Causal forest and R-learner selected equally well. | Double ML and AIPW, which estimate an average; pure risk model. | Case 8 |
| 5 | A/B test, many variables, form unknown | Effect per unit | Causal forest: CATE-RMSE 0.28, versus 0.45 for S-learner; it also provides confidence intervals. | R-learner, 0.36 | GLM with T × X, 0.74, or all two-way interactions, 1.08 | Case 8 |
| 6 | No randomization; confounders measured and effects linear | Average effect | LM with T + X | Double ML | Naive comparison | Case 2 |
| 7 | No randomization; confounders measured, effects nonlinear or unknown | Average effect | Double ML with a GBM as a building block | AIPW; causal forest | LM and S-learner, which were biased | Case 3 |
| 8 | No randomization; confounders measured | Ranking | R-learner or S-learner: top-30% uplift 2.70 and 2.71, respectively, versus the oracle’s 2.74. | Causal forest | Pure risk model | Case 9 |
| 9 | No randomization; confounders measured | Effect per unit | Causal forest: ATE bias −0.020 and CATE-RMSE 0.26. | R-learner, 0.34 | LM/GLM: ATE bias −1.76 despite correct ranking. AIPW produced no result in 21 of 40 runs. | Case 9 |
| 10 | No randomization; confounder missing, instrument available | Average effect | 2SLS for a constant effect; instrumental forest for a varying effect. | Placebo test (Case 5) | Methods that don’t use an instrument | Case 5 |
| 11 | No randomization; confounder missing, no instrument | Any effect question | No causal method. Report an association and use the E-value for sensitivity analysis. Before-and-after data or a threshold may support difference-in-differences or regression discontinuity; neither was simulated. | — | Any method that outputs an effect estimate | Case 5 |
The original article was first published on blog_philipppro and contributed to R-bloggers. Content issues can be reported here. R-bloggers invites submissions: contribute a blog, or use R-Posts if you don’t have one.
Checking estimates when the true effect is unknown
Real data can’t tell you directly whether an estimated treatment effect is right. The checks depend on the design: with randomized A/B data, use a hold-out set to assess the Qini or uplift curve and calibration. Without random assignment, the R-loss can rank methods only if the identification conditions from step 3 hold. A placebo test and an overlap histogram add useful diagnostics, but they don’t establish that those conditions are satisfied. Agreement among estimators can be misleading. In Cases 4 and 5, every method points to the same answer—and every method is wrong. That’s a useful warning against treating consensus as validation. Report uncertainty with a confidence interval (see Methodology, “Confidence intervals”), but read it narrowly: it captures random error. If step 3’s assumptions fail, even a very tight interval can miss the true effect. More detail appears in “Evaluation without knowing the truth.”When a simpler model is the better choice
Keep the simplest model that fits the problem as your baseline. A more complex estimator earns its place only when validated data show a clear improvement. In Cases 1, 2 and 6, the extra complexity adds no value. Several settings weren’t tested in the simulations: more than 100 variables with weak heterogeneity; trimming under weak overlap; weak instruments; incomplete compliance; panel or time structures; multiple treatment levels; continuous treatment; and methods covered in “Further methods (not simulated),” including BART, BCF and TMLE. Claims about those settings rest on methodological knowledge, not these simulations.Decision aids still need causal judgment
There’s no fully automatic way to choose the right causal method from data alone. The data can’t tell you whether a variable is a confounder or a mediator; that distinction requires knowledge of how the system works, expressed in a cause-and-effect diagram, or DAG. Automation can help once that diagram exists. - **DAGitty [26]** lets you draw a DAG and identifies variables to include in the model, along with possible instruments. It automates step 3.1. - **DoWhy [27]** follows the DAG through identification and estimation, then runs checks such as placebo tests, adding a random confounder, and using subsamples. It comes closest to an automated workflow. - **EconML Library Flow Chart [28]** guides estimator choice much like step 4, while also asking about compliance and whether effects vary linearly with features. - **Causal Roadmap [24]** and **Target Trial Emulation [25]** provide standardized workflows from epidemiology: define the experiment you would ideally run, then assess how closely the available data match it. - **Automatic model selection for CATE**, such as `causaltune` built on EconML, picks an estimator using R-loss or similar measures. That ranking is meaningful only when identification holds; see “Evaluation without knowing the truth.”Methodology
This section lays out what the study estimates and how: the core concepts, terminology, methods and formulas, and ways to evaluate estimates when real data don’t reveal the true effect.Core idea
Prediction and causal estimation answer different questions. LM, GLM and GBM are usually trained to predict \(Y\). Causal machine learning instead estimates how treatment \(T\) changes \(Y\), either on average (ATE) or for units with particular characteristics (CATE). A model that predicts outcomes well may still estimate effects poorly. And when the underlying relationship is simple, a more elaborate effect model has no automatic advantage. The study uses simulation because real data never expose the true treatment effect for each unit. Here, the data generating formulas are specified, so the true individual effects are known and each method can be compared with them directly. Following Molnar [6], the report takes a causal inference perspective—asking what causes what—and uses supervised learning tools such as GBM as components, for example in Double ML. It evaluates methods in the frequentist sense, by measuring bias and spread across repeated samples. Other perspectives lead to different tools: Bayesian methods include BART and Bayesian causal forest, which represent unit-level uncertainty with a posterior; reinforcement learning uses bandits that assign treatment continuously and learn as they go. That produces a different kind of data from the one studied here. The key distinction holds across these approaches: strong prediction alone doesn’t guarantee strong causal estimates. Introductions to the field: [1, 2, 3].Terms
**Potential outcomes.** Each unit has two possible outcomes: under treatment (
 ) and
 without treatment (
 ). Only one outcome is observed. Their difference,
 , is the individual effect.
| Term | Definition |
|---|---|
| ATE (Average Treatment Effect) | \(\text{ATE} = E[Y(1) – Y(0)]\): the average effect across all units. |
| CATE (Conditional ATE) | \(\tau(x) = E[Y(1) – Y(0) \mid X = x]\): the effect among units with characteristics \(x\), often described as the effect “per unit.” |
| Treatment \(T\) | The action whose effect is being estimated, such as a call, discount or campaign. Treatment is binary (0/1) throughout this study. |
| Outcome \(Y\) | The result the action is intended to change; higher values are better. |
| Confounder | A variable that affects both \(T\) and \(Y\) (\(T \leftarrow X \rightarrow Y\)). Leaving it out mixes its effect with the treatment effect. It must be included in the model in the right functional form. |
| Mediator | A variable on the path from treatment to outcome (\(T \rightarrow M \rightarrow Y\)), arising after treatment. Adjusting for it removes the part of the total effect that passes through it, so it must be excluded when estimating the total effect. |
| Collider | A variable affected by both treatment and outcome (\(T \rightarrow C \leftarrow Y\)). Adjusting for it creates a spurious association between them. It must be excluded; here, the practical rule is the same as for mediators: don’t adjust for something that arises after treatment. |
| Instrument \(Z\) | A variable that changes treatment, affects the outcome only through treatment, and is unrelated to unobserved disturbances. A valid instrument can support effect estimation despite unobserved confounding. |
| Effect modifier | A variable that changes the size of the treatment effect—for example, price sensitivity affecting whether a discount works. It creates variation in \(\tau(x)\). |
| Noise variable | A variable that affects neither treatment nor outcome. It adds no systematic bias but reduces estimation precision. |
| Randomization | Treatment is assigned by chance, such as a coin flip. This removes confounding of treatment, making a simple difference in means unbiased. |
In the DAGs below, an arrow
 means that A enters the formula for B. Dashed arrows represent unobserved variables.
Methods
Most methods take training data and return an estimated effect
 for each test customer. The exception is pure GBM: it ignores treatment and predicts risk instead.
| Method | Model | Assumption |
|---|---|---|
| Naive (difference in means) | \(\hat\tau = \bar Y_{T=1} – \bar Y_{T=0}\) | No confounding; treatment is randomized. |
| LM/GLM (T + X) | \(Y = \beta_0 + \tau T + \beta^\top X\) | Constant effect; \(Y\) is linear in \(X\), or logit-linear for binary \(Y\). |
| LM/GLM (T x X) | \(Y = \beta_0 + \tau_0 T + \beta^\top X + T \cdot \gamma^\top X\) | Effect varies linearly with \(X\). |
| LM/GLM (T x all 2-way X) | As above, with all products \(X_j X_k\) and their interactions with \(T\). | Effect is quadratic in \(X\). |
| GBM / LightGBM S-learner | One model \(\hat f(X,T)\); \(\hat\tau(x) = \hat f(x,1) – \hat f(x,0)\). | No functional form is imposed. Regularization can shrink the estimated treatment effect toward zero. |
| GBM / LightGBM T-learner | Separate models \(\hat f_1\) for treated units and \(\hat f_0\) for untreated units; \(\hat\tau(x) = \hat f_1(x) – \hat f_0(x)\). | No functional form is imposed, but each model uses only half the data, raising variance. |
| GBM / LightGBM pure (ignores T) | Predicts with \(\hat f(X)\), without \(T\); score is predicted risk \(-\hat f(x)\). | It is not an effect model. A common targeting approach is to predict churn risk, then call the highest-risk units. |
| Causal forest | `grf::causal_forest` | No functional form is imposed. It estimates \(\tau(x)\) directly, adjusting for propensity and baseline with honest trees. Defaults are used; ATE is the mean of CATE predictions. |
| Double ML (xgboost) | Five-fold cross-fitting estimates \(\hat\ell(X) \approx E[Y \mid X]\) and \(\hat m(X) \approx E[T \mid X]\), then \(\hat\tau = \frac{\sum_i (T_i – \hat m_i)(Y_i – \hat\ell_i)}{\sum_i (T_i – \hat m_i)^2}\). | Assumes a constant effect, or estimates a weighted mean; confounders may be arbitrarily nonlinear. It uses the same xgboost as the S-learner, but residualizes \(T\) and \(Y\) on \(X\) first so regularization does not bias the effect. |
| R-learner (xgboost) | Uses the same residuals \(\tilde Y, \tilde T\) as Double ML; xgboost estimates \(\hat\tau(x)\) from \(\tilde Y / \tilde T\), weighted by \(\tilde T^2\). | No functional form is imposed for \(\tau(x)\); confounders may be arbitrarily nonlinear. It needs overlap: units with propensity near 0 or 1 contribute little. |
| AIPW (causal forest) | `grf::average_treatment_effect` on the causal forest: \(\hat\tau = \tfrac{1}{n}\sum_i \big[\hat\mu_1 – \hat\mu_0 + \tfrac{T_i (Y_i – \hat\mu_1)}{\hat e} – \tfrac{(1-T_i)(Y_i – \hat\mu_0)}{1 – \hat e}\big]\). | Doubly robust: valid if either the outcome model or propensity model is correct. Estimates an average effect, not unit-level effects. |
| 2SLS | First stage predicts \(\hat T\) from \(T \sim Z + X\); second stage fits \(Y = \beta_0 + \tau \hat T + \beta^\top X\). | Requires a valid instrument \(Z\) and a constant effect; this is the classical IV estimator. |
| Instrumental forest | `grf::instrumental_forest` | Requires a valid instrument \(Z\); effects may vary arbitrarily with \(X\). |
For xgboost and LightGBM, depth is 3 and learning rate is 0.1. The number of rounds is chosen by five-fold cross-validation with early stopping. Other settings use library defaults; LightGBM sets `num_leaves = 8` and `min_data_in_leaf = 20`.
Methods in detail
The methods below start with the S-learner. The notation uses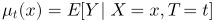 for expected outcome,
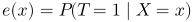 for propensity—the chance of receiving treatment—and
 for an estimate.
GBM S-learner (“Single”)
The S-learner fits one model to everyone and supplies as one of its features. To estimate the effect, it predicts twice for the same unit, switching treatment from 0 to 1 while holding other inputs fixed.

GBM T-learner (“Two”)
The T-learner fits one model to treated units and another to untreated units, then subtracts their predictions.
Pure GBM (ignores )
A pure GBM predicts without including treatment, as in a churn model. Its score is the predicted risk.

Double ML
Double ML first fits two nuisance models using: one predicts the outcome expected without treatment, 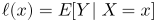 , and the other predicts treatment assignment,
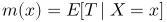 . Subtracting those predictions leaves residuals—the parts of outcome and treatment that \(X\) didn’t explain. The treatment effect is the slope relating those residuals.

 and
 enter as a product, allowing flexible models for confounders without introducing bias into the effect estimate. The tradeoff: standard Double ML estimates one effect for everyone, rather than a separate effect per unit. Source: [7]; textbook: [2].
R-learner (Double ML with per-unit effect)
The R-learner starts with the same residuals as Double ML, then replaces the single effect estimate with a function,
 . A flexible model learns which features explain the remaining outcome residuals:

 from , weighted by
 . Units with
 —propensity near zero or one—carry almost no weight. And when the true effect is constant, the model can invent apparent variation, adding more variance than Double ML. Source: [8].
Choosing an estimator means choosing what can go wrong
There’s no method here that wins across every setting. The simulation results make a more useful point: each estimator answers a different question, and each can fail in a different way. If you’re choosing one for a real decision, start with how treatment was assigned, which factors were measured, and whether you need an average effect or an effect for each unit. For a randomized A/B test, the difference in means is hard to improve on when you only need the average. It’s unbiased without model assumptions. Outside random assignment, though, it can mistake the influence of other variables for an effect; in Case 2, that bias was -2.82. When all relevant variables are measured and relationships are simple, a linear or generalized linear model is transparent and can perform well with little data. In Case 1, its CATE error was 0.141. But nonlinear influences produced bias of -1.75 in Case 3, and a single constant effect misses genuine variation, as in Case 8. Adding treatment interactions helps when the way effects vary is known: in Case 6, the interaction model’s error was 0.127, compared with 0.24 for the causal forest. With many unknown interactions, performance deteriorated: error reached 0.74, or 1.08 with all interactions in Case 8. In Case 9, it still ranked the top 30% well—2.73 against an oracle value of 2.74—even though nonlinear influences pushed its estimated magnitude off by -1.76. Boosting can be useful for finding who is likely to benefit, but the choice of learner matters. The GBM S-learner ranked units closely in Cases 8 and 9: 1.64 versus an oracle 1.65, and 2.71 versus 2.74. It takes little effort to apply, yet regularization can distort effect size under strong confounding; reported biases were -0.197 in Case 3 and -0.117 in Case 9. A T-learner gives treated and untreated groups separate models, which suits large samples and groups with different structures. With small samples, splitting the data between two models raises variance: its Case 1 CATE error was 0.72. A plain GBM that ignores treatment has a narrower job: predicting risk, such as who will cancel. It can select people likely to have an outcome rather than people likely to respond to an intervention. In Case 7, the top 30% had an effect of 0.037, worse than chance. Double ML is a practical choice for estimating an average effect when measured confounders act nonlinearly. It used a GBM as a building block and had bias of -0.013 in Case 3. But an average estimator cannot recover individual differences; its CATE error reached 1.50 in Case 9. The R-learner does estimate effects per unit, including when assignment isn’t random and the form of variation is unknown. Its errors were 0.36 in Case 8 and 0.34 in Case 9, with rankings on a par with the causal forest. That flexibility can be wasted when effects are constant: it estimated differences that weren’t there in Case 1, with error 0.27 versus 0.150 for Double ML. It also trailed the causal forest in Cases 8 and 9. The causal forest is the stronger candidate when effects vary in an unknown way across many variables or nonlinear confounders. Its CATE errors were 0.28 in Case 8 and 0.26 in Case 9, and it provides confidence intervals. Yet complexity doesn’t guarantee an advantage: a suitable GLM won in Case 6, and the forest offered no benefit over a linear model with a small sample in Case 1. Weak overlap also makes it unstable. The reported results used default settings, not tuned ones. ### Average effects, overlap, and instruments AIPW combines an outcome model with a propensity model, using a weighted correction for observed outcomes. Its appeal is real: the estimate remains correct if either one of those models is correct. In Case 3, its bias was -0.059. But that protection depends on adequate overlap. When propensities approach zero or one, weights can explode: runs failed in Case 3, and 21 of 40 failed in Case 9. AIPW estimates an average effect, not an effect for each unit. TMLE is cited as a more stable variant. When an important confounder wasn’t measured, 2SLS can use an instrument: a variable that shifts treatment but has no other path to the outcome. The first stage isolates the treatment variation explained by the instrument; the second estimates the effect using that variation. With a binary instrument and no covariates, this reduces to the Wald estimator: the instrument’s effect on the outcome divided by its effect on treatment. The catch is fundamental. The data can’t establish that the instrument is valid, and a weak instrument makes the estimate highly uncertain because the first-stage effect is near zero. An instrumental forest applies the same instrument logic locally, estimating effects among similar units using forest weights. That lets effects vary across units, but with a constant effect it adds noise compared with 2SLS, as in Case 5. The practical lesson is less about finding a universal winner than ruling out methods that don’t match the problem. A risk predictor won’t answer an intervention question; an average effect won’t tell you who benefits; and a flexible estimator can’t rescue weak overlap or an invalid instrument. The reported cases offer evidence for those tradeoffs, not a guarantee that the same ranking will hold in every dataset.Causal forest
A forest of trees that split on differences in treatment effects across leaves, rather than differences in the outcome. For a new unit  , it uses training units that often land in the same leaf, weighted by
 , to estimate a local effect using residuals as in Double ML.

Honest: Half the data sets the splits; the other half estimates effects, reducing the chance that random fluctuations look like real effects. Weakness: Fine-grained differences need substantial data. If effects are constant or relationships are linear, the forest has no advantage. Sources: [10, 11]; honest trees: [12].
AIPW (doubly robust)
AIPW pairs an outcome model  , which predicts both potential outcomes for each unit, with a weighted correction based on observed outcomes. Units with low propensity receive more weight.

Doubly robust: The estimate is correct if either the outcome model or the propensity model is correct. Weakness: When  is close to 0 or 1, the weights
 can explode; individual runs fail (Case 3). It estimates an average effect only. Source: [13]; TMLE is cited as a more stable variant: [17].
2SLS (instrument  )
An instrument can help when a confounder is unobserved, provided it shifts treatment without another path to outcome . In stage one, 2SLS isolates the treatment variation explained by the instrument. Stage two estimates the effect using that variation, which is free of the unobserved confounder.

With a binary instrument and no , the estimator is the Wald ratio: the instrument’s effect on the outcome divided by its effect on treatment.

Weakness: The data can’t verify that is valid. If it barely shifts , the denominator approaches zero and uncertainty grows sharply. Source: [5].
Instrumental forest
An instrumental forest combines the IV logic of 2SLS with the local estimation of a causal forest. For each unit , it estimates an IV effect from similar units, weighted by . The effect can therefore vary with .

Weakness: If the effect is constant, it adds noise relative to 2SLS (Case 5). Source: [11].
Strengths and weaknesses by method
The simulation summary below connects each method to the conditions where it performed well or poorly. The guide addresses which one to choose; these results explain the tradeoffs.
| Method | Good for | Bad when | Evidence in report |
|---|---|---|---|
| Naive (difference in means) | Randomized A/B tests when only the average matters (Cases 1, 6–8). Unbiased, with no model assumptions. | Without random assignment, it attributes the influence of other variables to treatment (Case 2: bias -2.82). | Cases 1, 2, 6–8 |
| LM/GLM (T + X) | Constant effects, linear relationships, and measured confounders (Cases 1, 2). Hard to beat with a small sample (Case 1: CATE error 0.141); transparent and auditable. | Nonlinear confounders (Case 3: bias -1.75) or varying effects (Case 8). | Cases 1, 2, 3, 8 |
| LM/GLM with interactions (T × X) | Effects that vary in a simple, known way; it beat the causal forest in Case 6 (error 0.127 vs. 0.24). It can also rank units well when magnitude is biased (Case 9: top 30% at 2.73, oracle 2.74). | Many unknown interactions (Case 8: error 0.74; 1.08 with all interactions). Nonlinear confounders distort magnitude (Case 9: bias -1.76). | Cases 6, 8, 9 |
| GBM S-learner | Ranking in A/B tests and when confounders are measured (Case 8: 1.64 vs. oracle 1.65; Case 9: 2.71 vs. 2.74). Requires little effort. | Regularization can bias effect size under strong confounding (bias -0.197 in Case 3; -0.117 in Case 9). | Cases 3, 7, 8, 9 |
| GBM T-learner | Large samples in both groups, especially when treated and untreated units have different structures. | Small samples: two models each get half the data, raising variance (Case 1: CATE error 0.72). | Case 1 |
| Pure GBM (ignores T) | Risk prediction, such as identifying who will cancel. It doesn’t estimate intervention effects. | It may select high-risk units instead of high-effect units (Case 7: top 30% effect 0.037, worse than chance). | Case 7 |
| Double ML | Average effects with measured, nonlinear confounders (Case 3: bias -0.013). Can use a GBM as a building block; fast and easy to explain. | It estimates an average, so CATE error is high when effects vary (Case 9: 1.50). | Cases 3, 9 |
| R-learner | Unit level effects with unknown form, including without random assignment (CATE error 0.36 in Case 8 and 0.34 in Case 9). Rankings comparable to the causal forest. | When effects are constant, it estimates variation that isn’t there (Case 1: error 0.27 vs. 0.150 for Double ML). Less accurate than the causal forest in Cases 8 and 9. | Cases 1, 8, 9 |
| Causal forest | Unit level effects with unknown form, many variables, or nonlinear confounders (CATE error 0.28 in Case 8 and 0.26 in Case 9). Provides confidence intervals. | A suitable GLM does better for simple effects (Case 6). No advantage over LM with a small sample (Case 1). Unstable with weak overlap. Results used default, untuned settings. | Cases 1, 6, 8, 9 |
| AIPW | Average effects with protection against a misspecified outcome or propensity model (Case 3: bias -0.059), if overlap is adequate. | With weak overlap, propensities near 0 or 1 make weights explode and runs fail (2 in Case 3; 21 of 40 in Case 9). Doesn’t estimate unit level effects. | Cases 3, 9 |
| 2SLS / Instrumental forest | Unmeasured confounding when a valid instrument is available (Case 5). Use 2SLS for constant effects and an instrumental forest for varying effects. | Weak or invalid instruments. Validity cannot be established from the data; the simulation assumes it in Case 5. | Case 5 |


